Generative AI / LLM Engineering
Akarika
Multilingual RAG Document Assistant
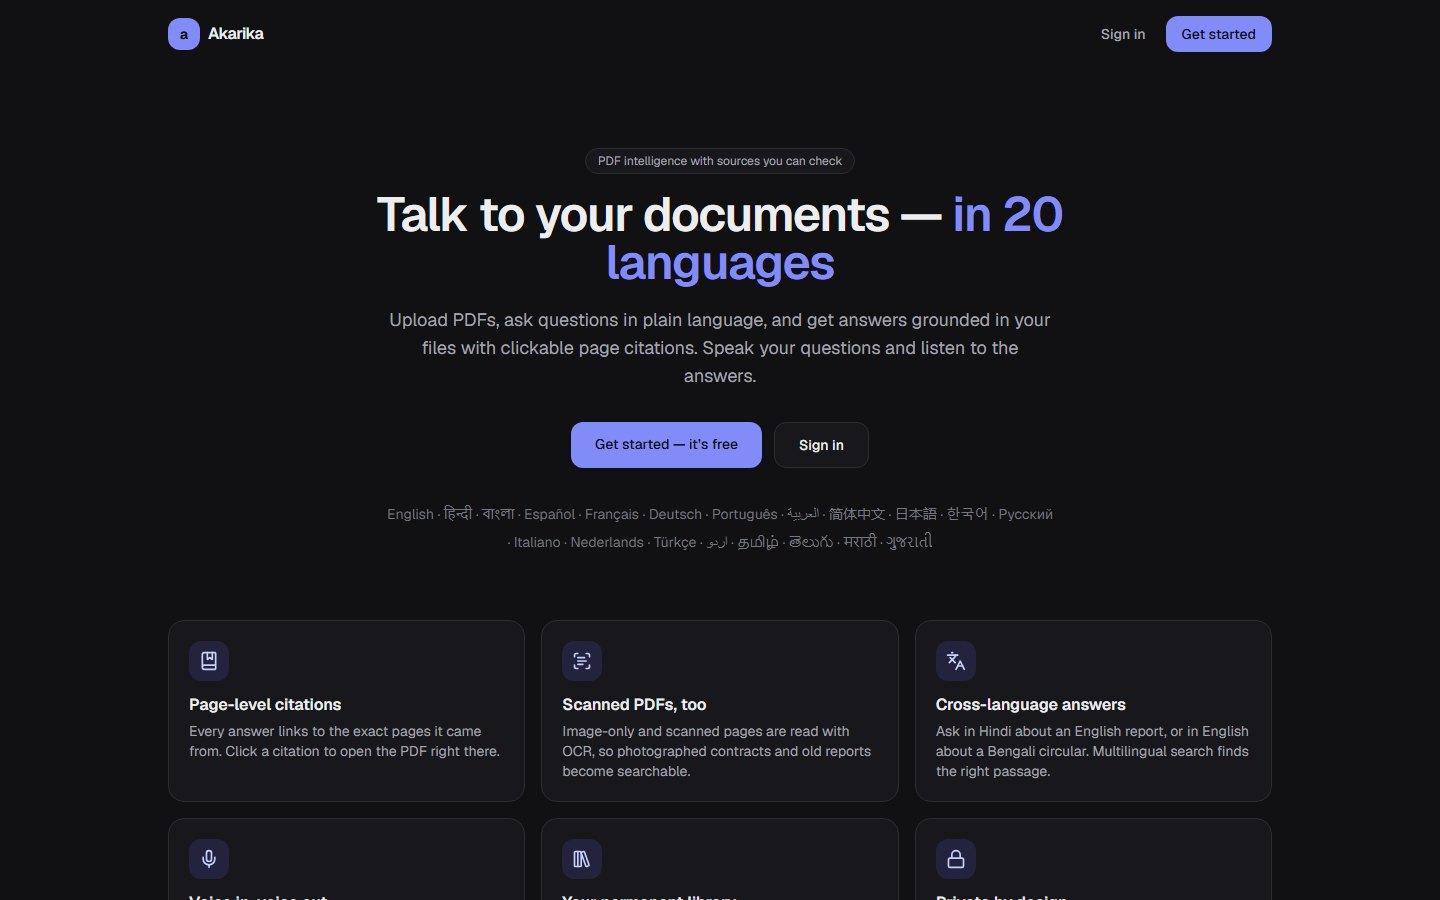
An end-to-end Retrieval-Augmented Generation app: upload PDFs, ask questions in natural language, and get answers grounded in the document with page-level citations, in 20 languages, by text or voice.
01Overview
A multilingual AI document assistant that lets anyone upload a PDF and hold a conversation with it, by typing or speaking, with every answer traceable to a page in the source.
Akarika is a production-deployed document assistant built around a complete RAG pipeline. Uploaded PDFs go through text extraction and chunking, the chunks are embedded and stored in a vector database, and each question triggers a semantic similarity search that retrieves the most relevant passages. The LLM answers using only that retrieved context and cites the exact pages it used, so every response can be checked against the source document. The app adds 20-language support, speech-to-text and text-to-speech, authentication and persistent chat history, and is deployed on Vercel.
02Problem
Long documents are slow to search manually, and LLM chatbots without retrieval can produce answers that are not grounded in the user's actual document. Users also need to work in their own language.
03Solution
A Retrieval-Augmented Generation pipeline grounds every answer in passages retrieved from the uploaded document and returns page-level citations, while multilingual support and voice input/output make the assistant usable across 20 languages.
04Architecture
- 01
PDF text extraction
Text is extracted from the uploaded PDF, page by page.
- 02
Document chunking
The text is split into chunks suitable for retrieval.
- 03
Embedding generation
Each chunk is converted into a vector embedding.
- 04
Vector storage
Embeddings are stored in a vector database.
- 05
Semantic similarity search
A question is embedded and matched against stored chunks to retrieve relevant context.
- 06
Grounded answer + citations
The LLM answers from the retrieved context and cites the source pages.
High-level pipeline stages. The specific LLM, embedding model and vector store will be documented here once published.
05Key Features
- PDF document upload
- Natural-language question answering
- Document chunking & context retrieval
- Vector similarity search
- Page-level source citations
- Support for 20 languages
- Speech-to-Text input
- Text-to-Speech answers
- Authentication
- Persistent chat history
06Technologies
- Python
- LLMs
- RAG
- Embeddings
- Vector Database
- Semantic Search
- Next.js
- Vercel
07Screenshots